tiktoken
Fast BPE tokenizer for OpenAI models: count tokens before they hit the context window.
Fast BPE tokenizer for OpenAI models: count tokens before they hit the context window.
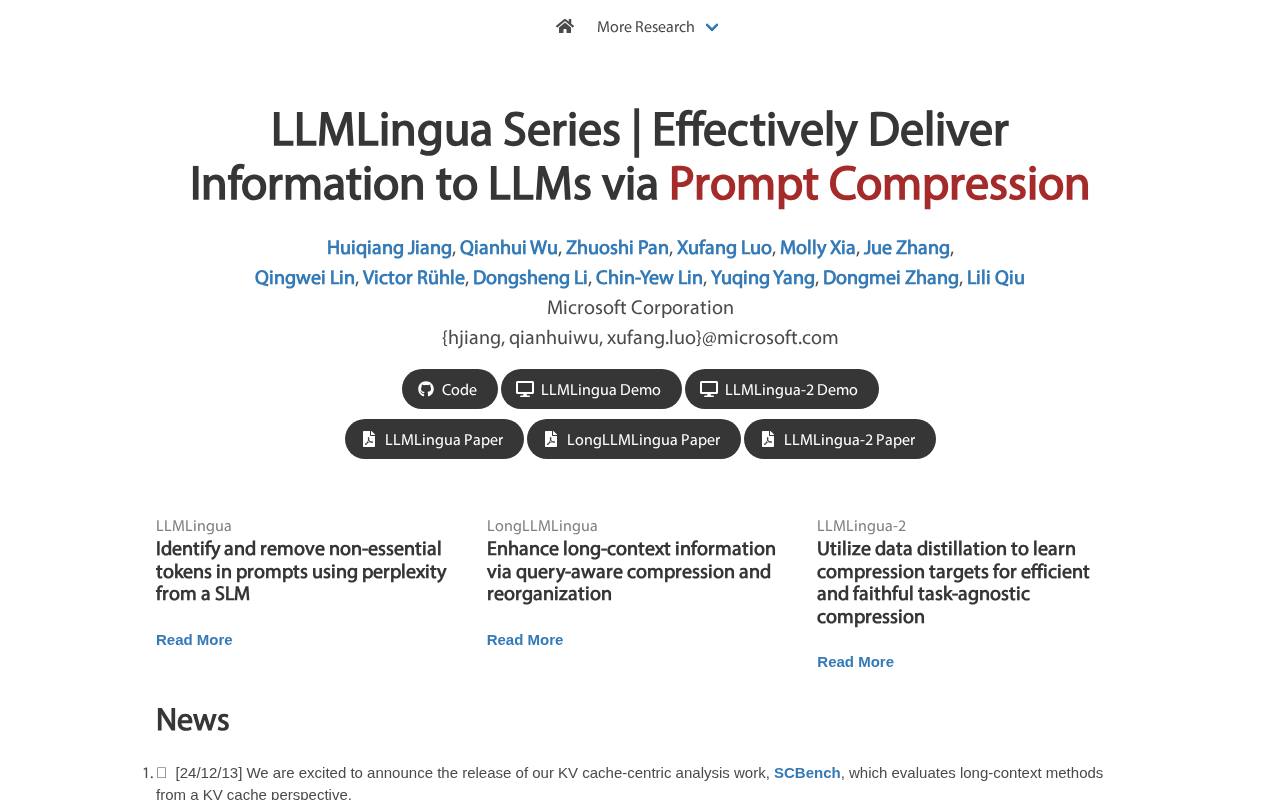
Microsoft's prompt-compression method: drops low-information tokens; the repo reports up to 20x compression.
Website captured Oct 19
Latest collected value
Latest collected value
Latest collected value
Latest collected value
Latest collected value
Latest collected value
Latest collected value
| Signal | tiktoken 7d | tiktoken 28d | LLMLingua 7d | LLMLingua 28d |
|---|---|---|---|---|
| PyPI downloads (last week) | ▲5.5% | ▲12.7% | ▲21.1% | ▲15.0% |
| GitHub stars | ▲0.2% | ▲0.9% | ▲0.2% | ▲0.9% |
| GitHub forks | ▲0.7% | ▲1.7% | ▲0.7% | ▲2.5% |
| Hacker News stories (7 days) | — | — | — | — |
| Hacker News points (7 days) | — | — | — | — |
| GitHub open issues & PRs | ▲0.7% | ▲4.2% | ▲0.0% | ▼0.8% |
| GitHub contributors | ▲0.0% | ▲4.0% | ▲0.0% | ▲0.0% |